 G2
 4.7/5

 Trustpilot
The web scraping tool for real-time, AI-ready data
24/7 testing on every actor. Fixes and adjustments within a few hours, so your data keeps flowing even when websites change.
Free usage every month. No credit card.
These teams already trust Evomi


Some of our top actors
Explore all actorsExplore all 645 actors

Google Maps Scraper
scrape.ly/store/cornerledger/google-maps-scraper Corner Ledger
Lead generationSEO tools


Instagram Profile Scraper
scrape.ly/store/echofield/instagram-profile-scraper Echofield
Social mediaLead generation


//02-Plug In. Power Up.\\
Connect Webhooks
with any of our Scrape.ly ActorsWebhooksYour data pipeline shouldn't stop at extraction. When a run finishes, Scrape.ly can POST to your URL, start another Actor, or trigger a saved task. Pushes to a linked GitHub repository rebuild your Actor, and AI agents can run Actors through the MCP server.


//
04
-
Dev First
\\
Built for builders. Loved by engineers.
Scrape.ly speaks your language - whether that's Python or JavaScript, Playwright or Puppeteer, REST or SDK.
Verified Source
Write less. Extract more with Scrape.ly Open Source Tools
Start from open-source Crawlee templates in JavaScript or TypeScript, then run any Store Actor from your own code with the API clients.

from scrapely_client import ScrapelyClient

client = ScrapelyClient(
    'YOUR_TOKEN',
    api_url='https://api.scrape.ly',
)

run = client.actor('username/my-actor').call(
    run_input={'url': 'https://example.com'},
)

dataset = client.dataset(run.default_dataset_id)
for item in dataset.iterate_items():
    print(item)


//06-Build Once. Keep Earning\\
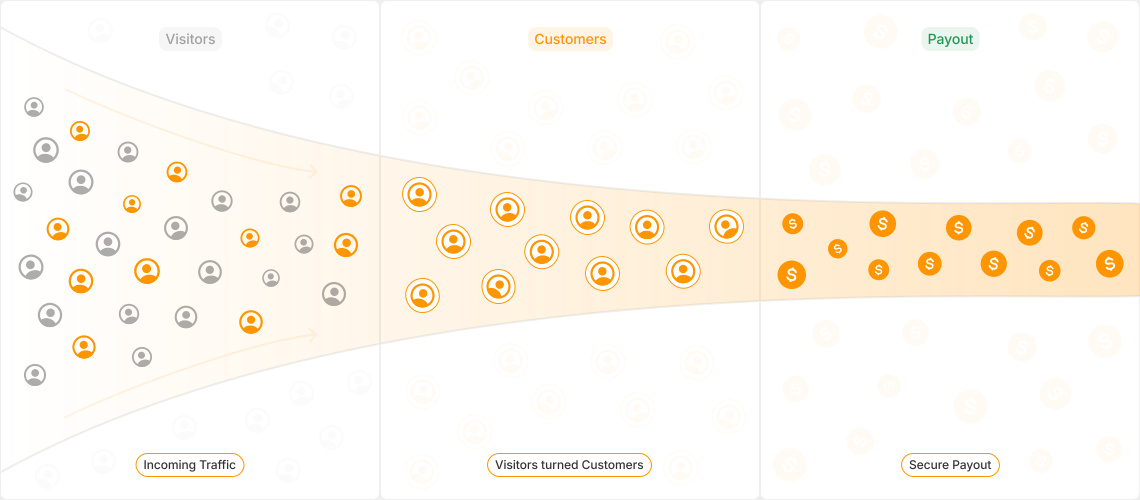
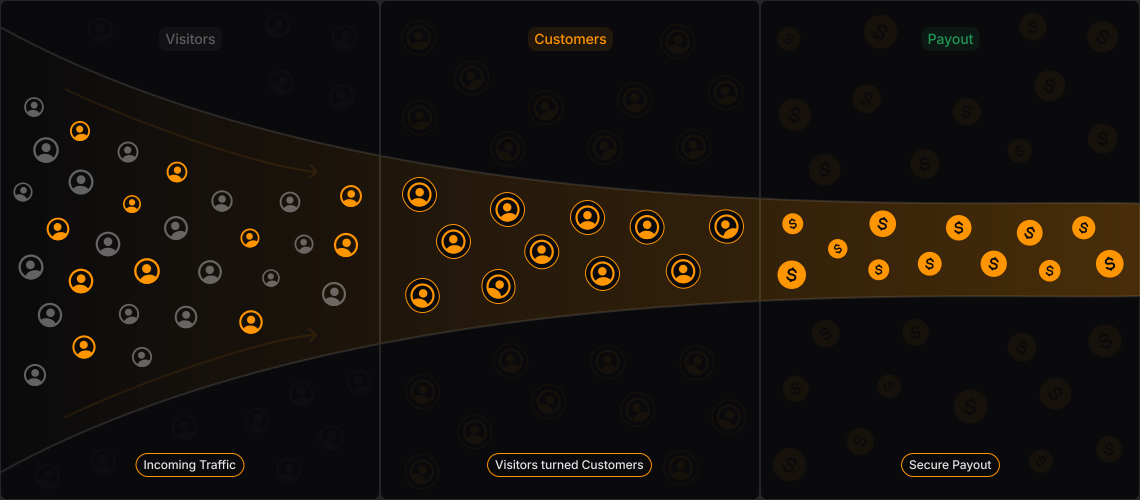
Turn your scrapers into a recurring revenue stream.
If you write code that extracts data, Scrape.ly wants to pay you for it. Publish your extractors on the Scrape.ly Marketplace
Zero Cost to Publish
Listing your Actor is free. Charge per event and earn 80% of what users pay with purchased credits. Users pay the platform usage on top, so nothing is deducted from your share - no upfront investment required.
We Handle Everything Else
Scaling, proxy management, uptime, storage - Scrape.ly's infrastructure carries the weight. You write the logic. We keep it running at scale.
Payouts on Request, No Headaches
Skip the invoicing hassle. No payment chasing. Scrape.ly handles all billing, and you request a payout by crypto, PayPal, or bank transfer whenever your balance reaches the minimum.
//07-Enterprise-Grade\\
Security, compliance, and reliability without compromise
Our enterprise tier delivers the controls, SLAs, and dedicated support your team demands.
Switched from running my own Puppeteer fleet. Last month cost $38 for about 1.2M page loads, less than one small VM used to. Porting my ten scrapers took two evenings; the tenth I gave up on and now use somebody else's actor from the store.
Nov 2025
VerifiedBackend Developer
ticketing aggregator, 8-person team
Proxy rotation used to eat half my week. Now I pick the country and go.
Dec 2025
VerifiedGrowth Marketer
40-person DTC brand
We do about 40k requests a day for a price-monitoring product. Good months are near 99%, bad ones are around 93% when a retailer reshuffles their frontend. Support has been quick during those.
May 2026
VerifiedFounder
price-monitoring SaaS
//From the blog\\
Latest articles
 Guides
Web Scraper Chrome Extensions: 4 Good Ones, and When to Use a Cloud Scraper
The best web scraper Chrome extensions in 2026 (Web Scraper, Instant Data Scraper, Data Miner and Evomi Web Data), what each is good at, where every extension stops, and how a cloud scraper takes over for schedules, thousands of pages and API access.
Read the article AI agents
12 Best MCP Servers in 2026: Web Data, Code, Docs and Browsers
The best MCP servers in 2026, grouped by job: web data, documentation, code, browsers, errors, databases and the official reference servers. Each with its hosted URL or install command, how it signs in, and the caveats its own README states.
Read the article Guides
n8n Puppeteer Node: Puppeteer and Playwright in n8n Without Self-Hosting Chrome
The n8n Puppeteer node needs Chromium inside your n8n container and installs only on self-hosted n8n. How it and the Playwright nodes install, where they break, and how to run the same browser scrape on Scrape.ly from n8n instead, with a real tested run.
Read the article
 G2
 4.7/5

 Trustpilot
The internet is full of data.
Start owning yours.
Scrape.ly gives you the infrastructure, the tooling, and the team to extract, process, and operationalize web data at any scale. Setup takes minutes.
No credit card. No setup calls.